
Google Launches Multimodal Knowledge Agent Benchmark to Evaluate Visual Reasoning in AI
Image: Google · Source
Google, in collaboration with Artificial Analysis, has introduced the Multimodal Knowledge Agent benchmark to assess AI agents' ability to handle visually complex, real-world tasks across various professional domains.
Google, partnering with Artificial Analysis, announced the launch of the Multimodal Knowledge Agent (MKA) benchmark on November 10, 2026. This new benchmark is designed to evaluate how artificial agents reason over visually complex tasks that typically arise in professional knowledge work. Unlike traditional benchmarks solvable with text alone, MKA emphasizes the importance of interpreting images, layouts, and schematics—elements critical to day-to-day operation in many industries.
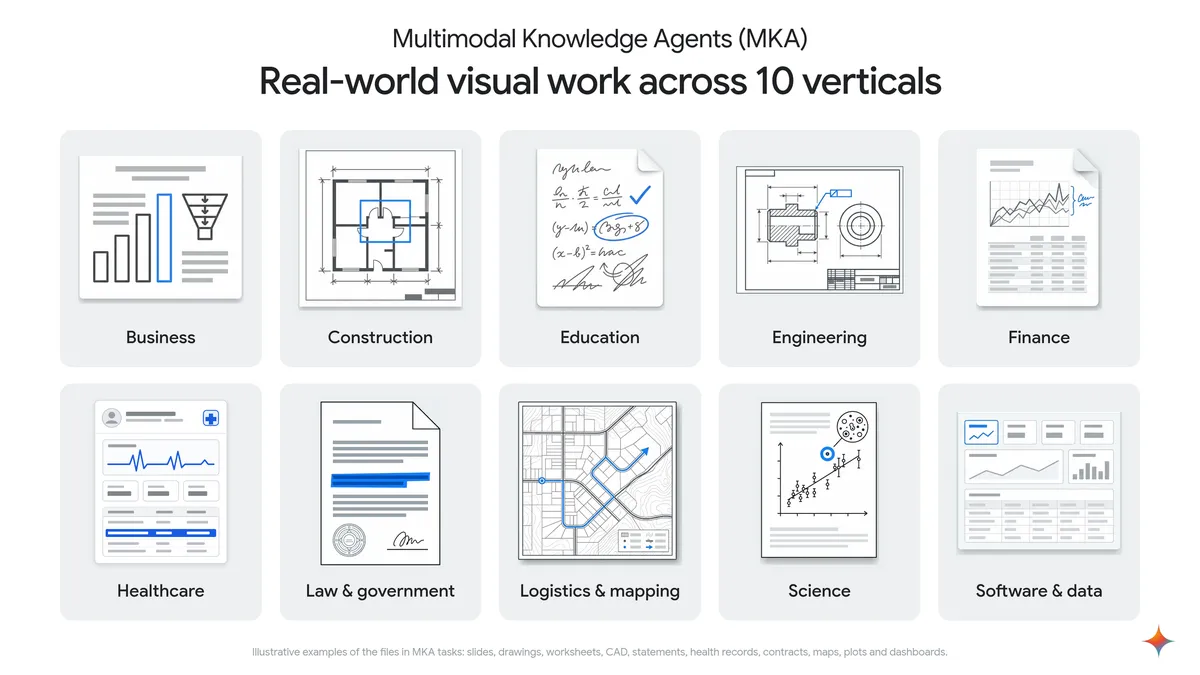
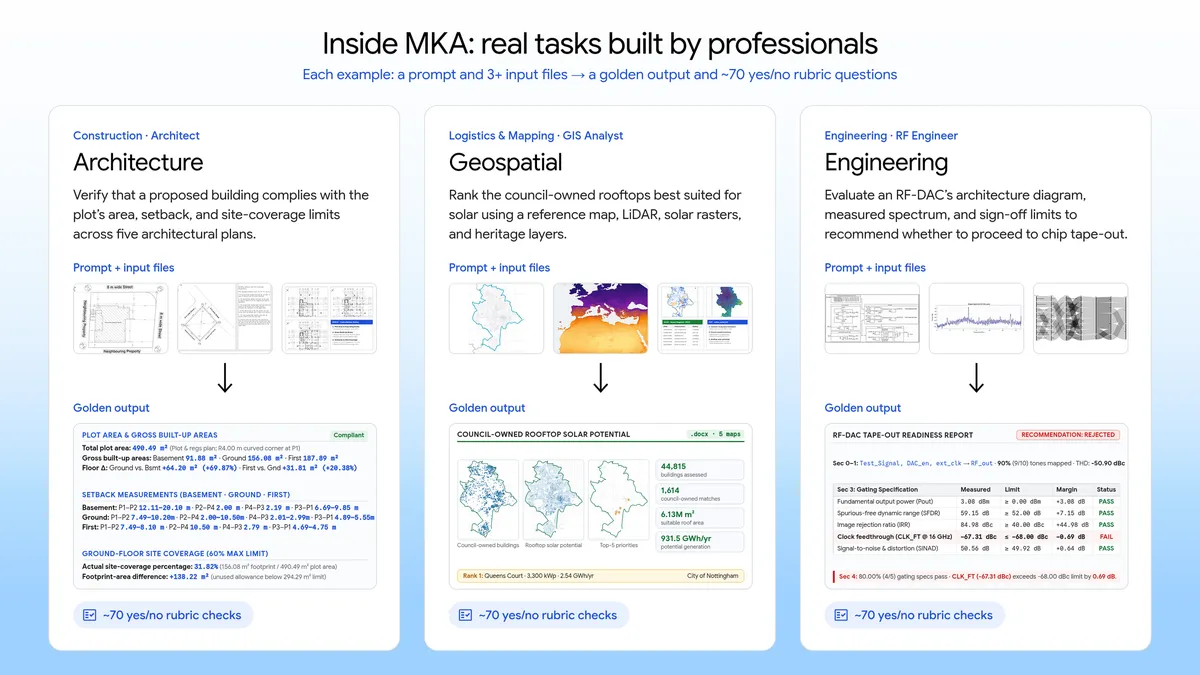
The MKA benchmark's creation involved domain experts from 10 verticals encompassing 83 occupations, including architects, biologists, underwriters, and data scientists. These specialists developed an evaluation set of 200 complex tasks that represent multi-step projects requiring several hours to complete by seasoned professionals. Each task contains realistic prompts paired with multimodal input files and is assessed using an expert-written rubric focused 75% on factual accuracy and 25% on visual design quality.
To facilitate fair and open benchmarking, all models evaluated with MKA operate within the open-source agent harness called Stirrup, which standardizes tools, sandbox environment, and interaction budget. Additionally, an agentic autorater built on a non-Google model automatically grades deliverables by thoroughly examining input files, rendering pages, inspecting spreadsheet formulas, and comparing outputs to expert rubrics. This autorater aligns with human expert judgment 96% of the time.
The evaluation data set remains private to prevent leakage into training data or model discovery through search, while a smaller public set of 10 tasks is available on Hugging Face for broader inspection and testing.
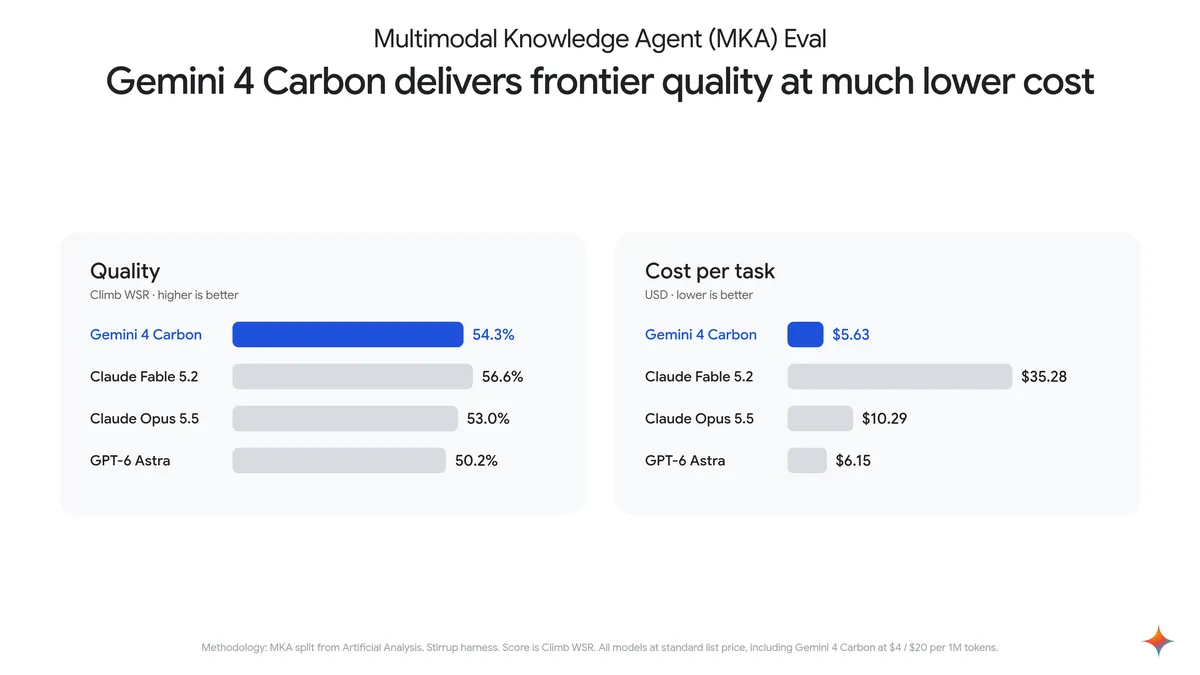
Google’s Gemini 4 Carbon model achieved the second-highest quality score on the MKA tests while demonstrating high cost efficiency—operating at roughly one-sixth the cost of the top-scoring model. Gemini 4 Carbon is accessible now through the Gemini API in Google AI Studio, supported by an updated developer guide.
The technical report accompanying MKA highlights that top-tier models differ significantly in efficiency and that strong visual perception capabilities are essential to solving the benchmark tasks. It also details how models underperform without visual inputs and the varied approaches agents take across these challenging tasks.
This initiative underscores the growing recognition that advanced AI agents must integrate multimodal understanding to effectively support complex, visually rich knowledge work across diverse fields.
Sources and original reporting
Read the original source ↗
Comments (0)
No comments yet. Start the discussion.
Write a comment
Comments are published after moderation. Your name and comment will be visible publicly. Account