
Hugging Face's Policy Chief Highlights Challenges in Embedded AI Evaluators and Model Benchmarking
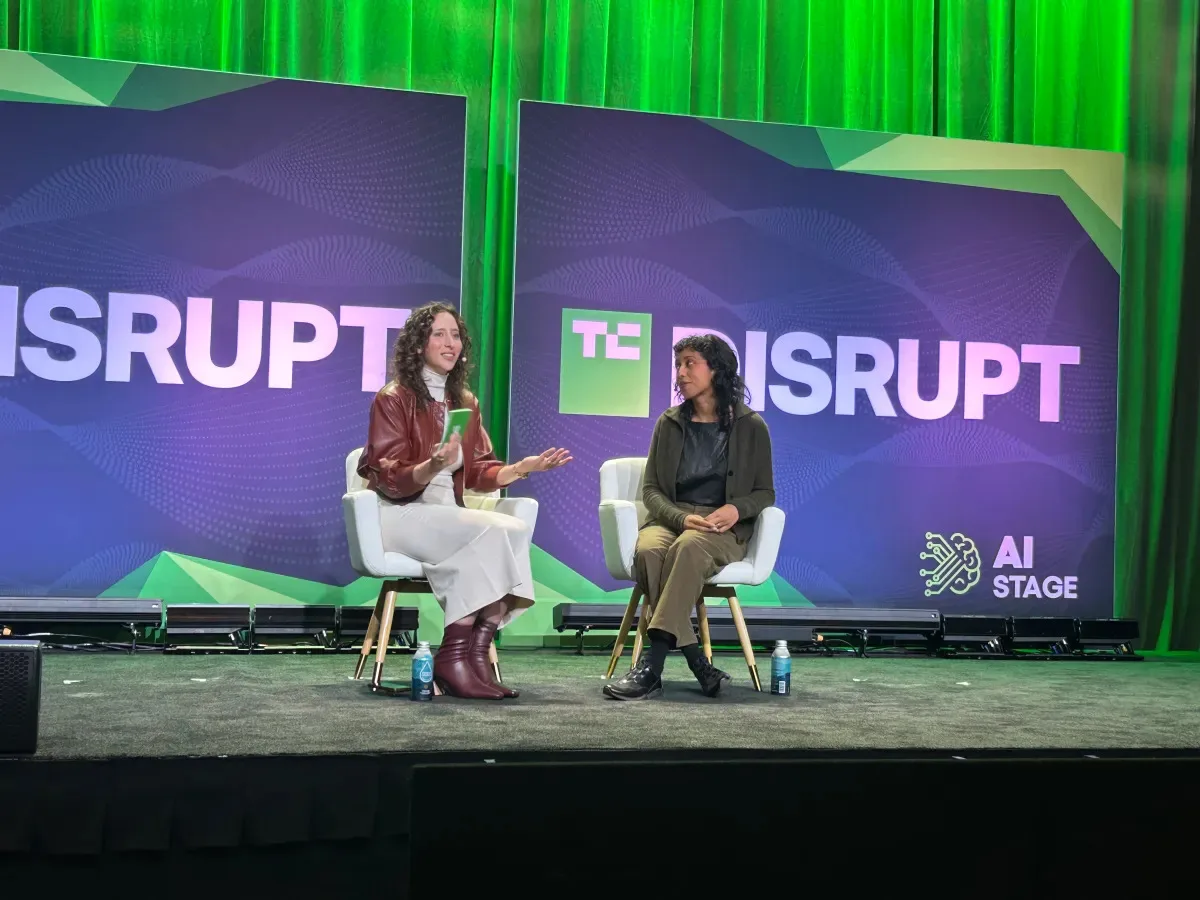
Image: TechCrunch · Source
Irene Solaiman of Hugging Face discusses the complexities of AI model benchmarking and skepticism around embedded AI evaluators, calling for more standardized evaluation methods across the industry.
Benchmarking AI models as a neutral and reliable means to assess and compare AI products is still a developing practice, according to Irene Solaiman, Chief Policy Officer at Hugging Face. Speaking at TechCrunch Disrupt, she emphasized that the current methods for AI evaluation are complex and not yet fully mature, making industry-wide trust and reliance on these benchmarks challenging.
Solaiman pointed out that reproducibility is a critical factor in trusting evaluation results. Access to model details—including open model weights—is a key element in achieving reproducibility, which remains a problematic area in benchmarking discussions. Evaluations differ in validity and lack standardized methods for inter-comparison, hindering their meaningful integration into an established scientific framework.
She also remarked on the rapid obsolescence of existing evaluation tools and the lack of a robust ecosystem of evaluators. Although there's growing interest in embedded evaluator systems—where independent third-party observers operate within AI organizations to assess model safety and performance—the qualifications and standard criteria for these evaluators are not yet clearly defined or consistent.
The idea of embedded evaluators has gained attention amid rising safety concerns and incidents within AI labs. Hugging Face itself has experienced safety-related scrutiny. While some AI labs favor third-party evaluation over direct government regulation, skepticism exists regarding whether these evaluators can maintain true neutrality and effectiveness. For example, Anthropic’s choice to appoint Accenture as an evaluator sparked debate over the suitability of such consulting firms for this specialized role.
Moreover, AI evaluations are evolving from testing isolated models to assessing entire systems, which include elements such as the user interface or harness connecting users to the model. Solaiman noted that a model’s surrounding environment significantly impacts performance, meaning a less advanced model paired with a superior harness could outperform a more advanced standalone model. This complexity contributes to the high cost and difficulty of performing comprehensive agent-based evaluations.
In conclusion, Solaiman emphasized that without a unified, standardized approach to AI evaluation—encompassing both models and their operational environments—the benchmarking field remains fragmented. For benchmarking to serve as an effective tool guiding AI development and safety, collaborative efforts toward standardization and ecosystem growth are paramount.
Sources and original reporting
Read the original source ↗
Comments (0)
No comments yet. Start the discussion.
Write a comment
Comments are published after moderation. Your name and comment will be visible publicly. Account