
Tenstorrent Galaxy Achieves 5,300 Tokens per Second Decode Speed on OpenAI’s gpt-oss-120b Model
Image: Tenstorrent · Source
Tenstorrent's Galaxy system runs OpenAI’s gpt-oss-120b at up to 5,300 tokens per second per user using eight connected Galaxy clusters, leveraging a Mixture-of-Experts architecture and efficient hardware design.
Tenstorrent has demonstrated industry-leading performance by running OpenAI’s open-weight language model, gpt-oss-120b, achieving decoding speeds of up to 5,300 tokens per second per user on a cluster of eight Galaxy systems. This performance represents significant advancement in efficient large model inference for responsive AI applications.
The gpt-oss-120b model employs a Mixture-of-Experts (MoE) architecture, where each token is routed through only 4 of 128 expert components rather than activating the entire model. This selective activation enables the model to use roughly 5.1 billion out of its 117 billion parameters per token, enhancing computational efficiency without sacrificing accuracy.
Tenstorrent’s Galaxy system integrates 32 Blackhole chips in a compact 6U server, equipped with 6.2 GB of high-bandwidth on-chip SRAM and 1 TB of GDDR6 DRAM. The architecture prioritizes keeping data close to compute units to reduce latency, employing SRAM for critical expert weights storage and streaming the remainder from DRAM. Galaxy systems interconnect over standard Ethernet, facilitating flexible scaling from a single server to multi-machine clusters.
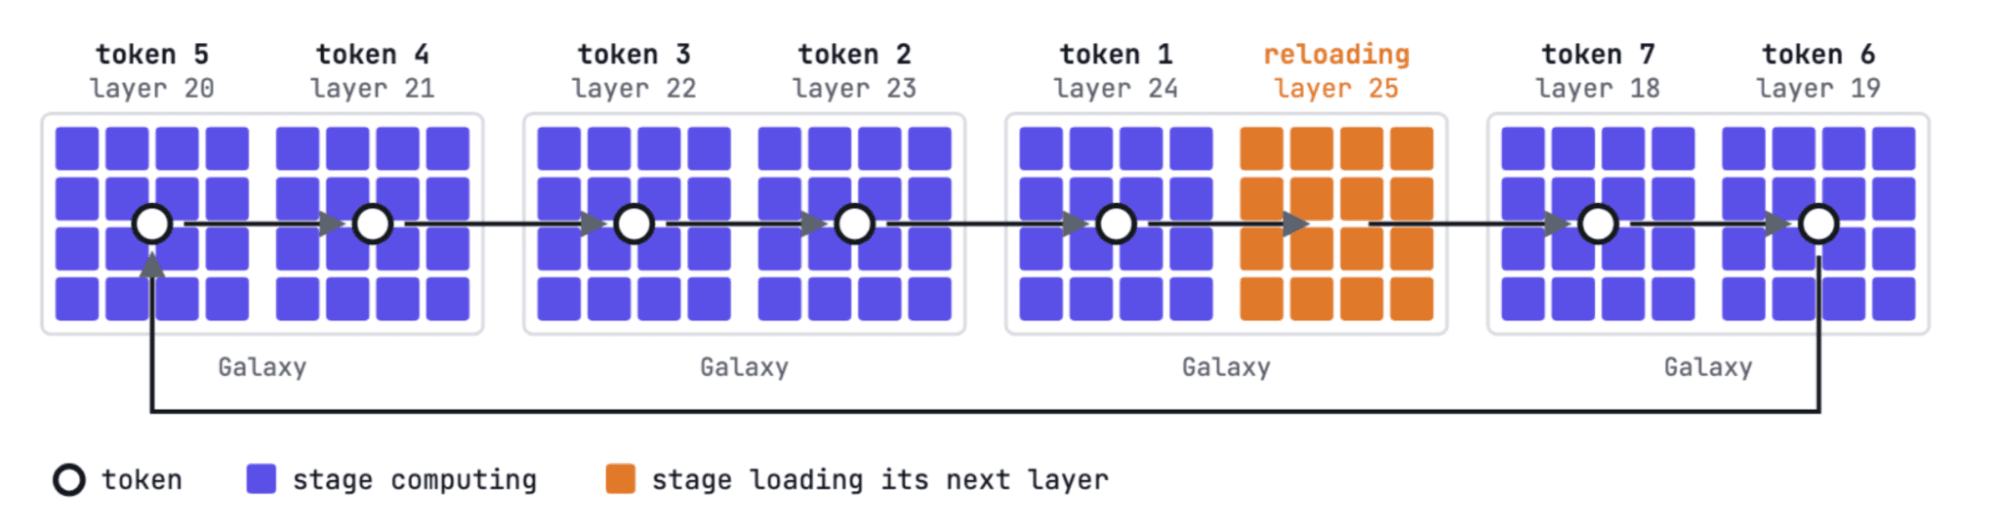
The deployment architecture divides each model layer across a 4×4 mesh of 16 Blackhole chips. The system reuses pipeline stages—while one stage processes the current layer, the next layer’s weights load into SRAM—maximizing hardware utilization. Chips pass activations between stages through direct, low-latency Ethernet links arranged to mirror physical cabling, enabling efficient distributed computation across multiple machines.
Testing on the GSM8K dataset, which consists of approximately 8,500 grade-school math word problems requiring stepwise reasoning, Galaxy averaged 3,000 tokens per second per user with an accuracy score of 95.8%. Peak speeds reached 5,300 tokens per second per user, focused on decode operations with short prompts, excluding initial token generation latency.
This demonstration highlights Tenstorrent’s ability to deliver fast, accurate, and scalable inference for large MoE models on open hardware. Organizations planning deployments requiring low-latency AI inference may evaluate Galaxy’s capabilities for balancing performance, scalability, and cost. The modular nature of Galaxy supports gradual scaling from single-unit setups to extensive multi-node clusters.
Tenstorrent continues to innovate in efficient AI accelerator design, emphasizing streamlined data movement and balance between memory capacity and compute proximity. Interested parties can contact Tenstorrent for further details or explore Galaxy for their AI inference infrastructure needs.

Sources and original reporting
Read the original source ↗
Comments (0)
No comments yet. Start the discussion.
Write a comment
Comments are published after moderation. Your name and comment will be visible publicly. Account